


Introduction to the Attention Mechanism in Transformers
What Is Attention?
Attention is like when you read a sentence and your brain decides which words matter most for understanding its meaning.
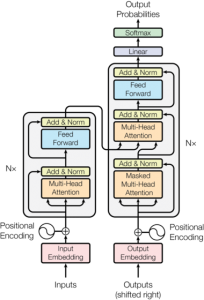
Introduction to the attention mechanism in Transformers
Scaled Dot-Product Attention
It is a mathematical formula that works like this:
- Compare: It takes one word (the query) and compares it with all the other words (the keys)
- Compute weights: It gives more importance to the most closely related words
- Combine: It blends all the information according to those weights
Formula: Attention(Q,K,V) = softmax(QK^T/√dk)V
Multi-Head Attention
Instead of using a single attention “head,” it uses several (8 in this case):
- Each head focuses on different aspects of the relationships between words
- It is like having 8 different perspectives on the same text
- At the end, all the perspectives are combined
Three Uses in the Transformer:
- Encoder-Decoder: The decoder looks at the entire input
- Encoder self-attention: Each word looks at all the others in its layer
- Decoder self-attention: Each word looks only at the previous ones (it cannot “cheat” by seeing the future)
In short: It is a mechanism that helps the model understand which parts of the text are most relevant to each word.
In the formula Attention(Q,K,V) = softmax(QK^T/√dk)V, the T stands for transpose.
What Is the Transpose?
The transpose of a matrix means flipping the matrix by swapping rows and columns.
Example:
Original matrix K:    Transpose K^T:
[1  2  3]            [1  4]
[4  5  6]            [2  5]
                     [3  6]
Why Is K^T Used?
To be able to perform matrix multiplication between Q and K:
- Q has dimensions: (number of queries × dk)
- K has dimensions: (number of keys × dk)
- K^T has dimensions: (dk × number of keys)
Therefore:
- Q × K^T = (number of queries × dk) × (dk × number of keys)
- Result = (number of queries × number of keys)
This gives us a matrix in which each element represents how compatible each query is with each key.
In Python code:
scores = torch.matmul(query, key.transpose(-2, -1))The .transpose(-2, -1) is equivalent to applying the T (transpose).
dk is the dimension of the keys and queries.
Simple Definition
dk = the number of elements (features) in each key and query vector.
In the Context of the Transformer
According to the paper:
- dk = dv = dmodel/h = 64
Where:
- dmodel = total model dimension (for example, 512)
- h = number of attention heads (8 in this case)
- dk = 512 ÷ 8 = 64
Why Is It Important?
It is used in two key places:
- In the division by √dk:
scores = QK^T / √dk- If dk = 64, then √dk = 8
- This normalizes the scores to keep them from becoming too large
- In the matrix dimensions:
- Each query vector (Q) has 64 elements
- Each key vector (K) has 64 elements
- Each value vector (V) also has 64 elements
Why Divide by √dk?
As the paper explains: when dk is large, the QK^T dot products become very large, causing the softmax function to have extremely small gradients. Dividing by √dk stabilizes training.
Example: If dk = 64, we divide by √64 = 8 to keep the values within a reasonable range.