
Editorial archive of Creangel. The references, figures and conditions correspond to the original publication.
Introduction to the Attention Mechanism in Transformers
What is Attention?
Attention is like when you read a phrase and your brain decides which words are most important to understand the meaning.
Introduction to the Attention Mechanism in Transformers
Scaled Dot-Product Attention
It's a mathematical formula that works like this:
- Compare: Take a word (query) and compare it with all other words (keys).
- Calculate Weights: Gives More Importance to the Most Related Words
- Combine: Mix all information according to those weights
Formula: Attention(Q,K,V) = softmax(QK^T/√dk)V
Multi-Head Attention
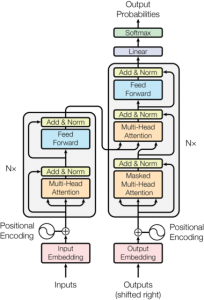
Instead of using a single “head” of attention, use several (8 in this case):
- Each head focuses on different aspects of the relationships between words
- It's like having 8 different perspectives from the same text.
- At the end all perspectives are combined
Three Uses in Transformer:
- Encoder-Decoder: The decoder looks at the entire input
- Encoder self-attention: Each word looks at all other words in its layer.
- Self-attention in Decoder: Each word only looks at the previous ones (can’t “cheat” seeing the future)
In short: It is a mechanism that helps the model understand which parts of the text are most relevant to each word.
In the formula Attention(Q,K,V) = softmax(QK^T/√dk)V, T means transpose.
What is the transposition?
The transposition of a matrix means turning the matrix by swapping rows into columns.
Example:
Original matrix K: Transposed K^T:
[1 2 3] [1 4]
[4 5 6] [2 5]
[3 6]
Why is K^T used?
To be able to multiply matrices between Q and K:
- Q has dimensions: (number of queries × dk)
- K has dimensions: (number of keys × dk)
- K^T has dimensions: (dk × number of keys)
Then:
- Q × K^T = (number of queries × dk) × (dk × number of keys)
- Result = (number of queries × number of keys)
This gives us a matrix where each element represents how compatible each query is with each key.
In Python code:
python
scores = torch.matmul(query, key.transpose(-2, -1))
The .transpose(-2, -1) is equivalent to setting the T (transposed).
dk is the dimension of keys and queries.
Simple Definition
dk = the number of elements (features) in each key and query vector.
In the Context of Transformer
According to the document:
- dk = dv = dmodel/h = 64
Where:
- dmodel = total model size (e.g. 512)
- h = number of attention heads (8 in this case)
- dk = 512 ÷ 8 = 64
Why is it important?
It is used in two key locations:
- In the division by √dk:
scores = QK^T / √dk
- If dk = 64, then √dk = 8
- This normalizes scores to keep them from being too large.
- In the dimensions of the matrices:
- Each query vector (Q) has 64 elements
- Each key vector (K) has 64 elements
- Each vector of value (V) also has 64 elements
Why Divide by √dk?
As the paper explains: when dk is large, the dot products QK^T become very large, causing the softmax function to have very small gradients. Dividing by √dk stabilizes training.
Example: If dk = 64, we divide by √64 = 8 to keep values within a reasonable range.